Projects / ServeScope
ServeScope
2026
Local inference lab for measuring interactive LLM latency under competing GPU workloads.
- Python
- vLLM
- PyTorch
- CUDA
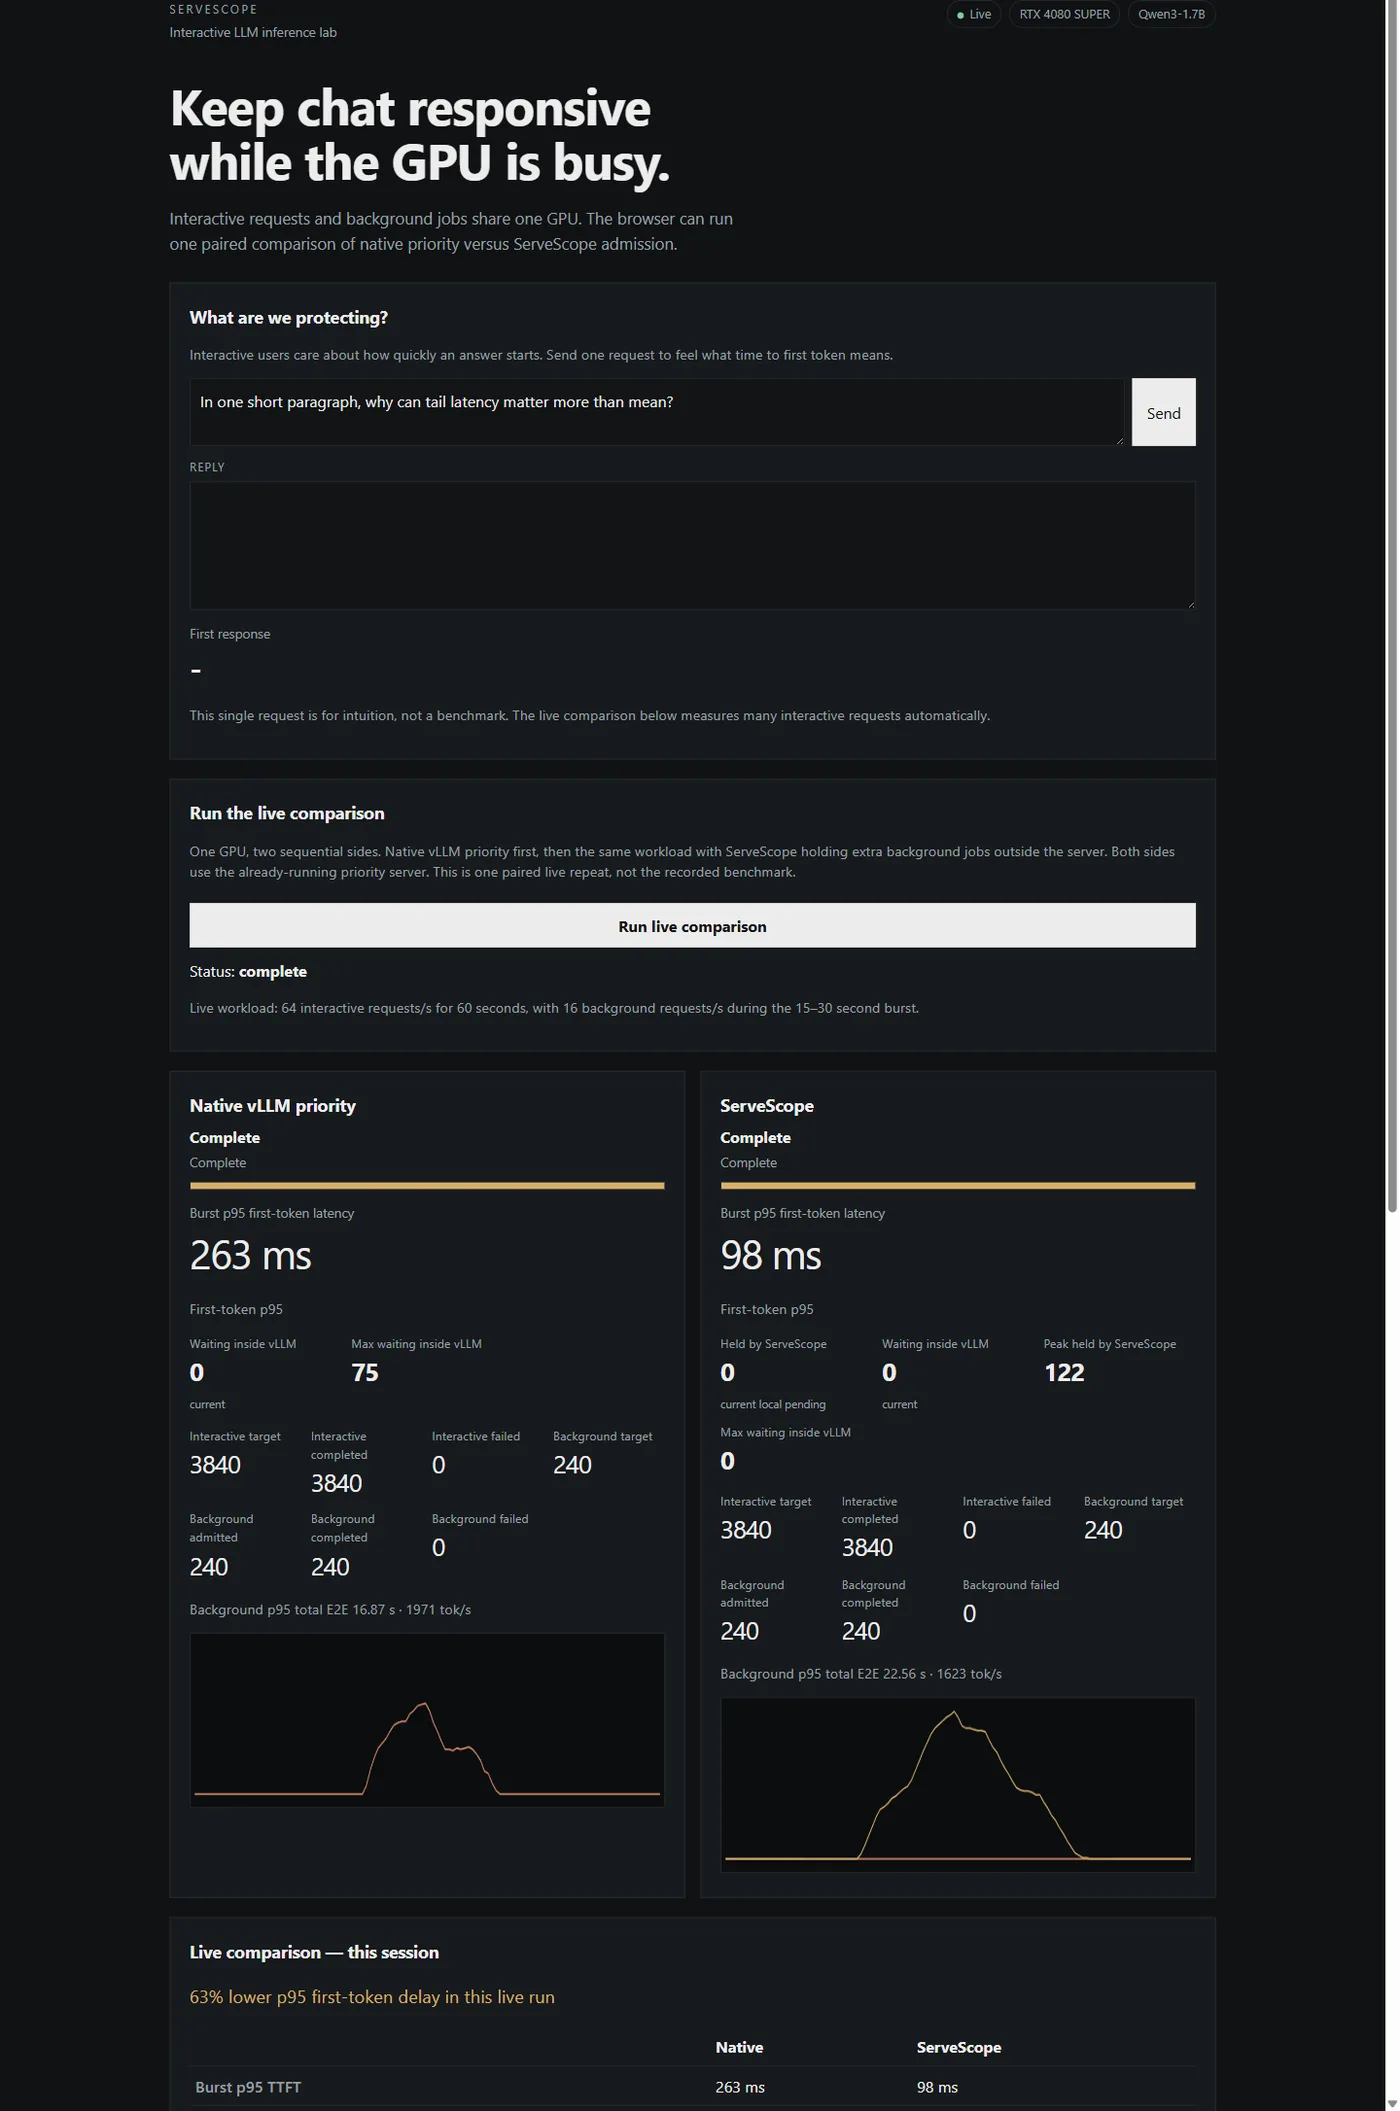
ServeScope keeps interactive LLM requests responsive when background jobs share the same GPU, by controlling how much background work enters the inference server.
It runs locally on an NVIDIA RTX 4080 SUPER. vLLM owns model execution, batching, KV cache, and GPU kernels.
What it does
- Streams chat against a local OpenAI-compatible vLLM server.
- Measures first-token latency with explicit client clocks.
- Runs mixed interactive and background workloads on vLLM 0.28.0 / Qwen3-1.7B.
- Compares vLLM
--scheduling-policy priorityagainst default FCFS. - Holds excess background work in an external admission queue.
- Shows the live experiment at
http://127.0.0.1:8080.
What I built
- Open-loop workload generation and traffic classes.
- Request-attempt / response-header / first-content / completion clocks.
- Validity checks that separate server delay from client dispatch failure.
- External bounded background admission (AIMD-style concurrency limit outside vLLM).
- Runtime queue and GPU telemetry on the demo page.
- Reproducible JSON/CSV artifacts and tests for metrics, backpressure, and demo behavior.
Results
Two separate benchmark sessions, not one four-stage latency progression.
Native priority baseline (artifacts/p3/comparison-2026-08-31T16-29-56Z/result.json)
Default FCFS mixed burst p95 TTFT 3.33 s. Native vLLM priority 836 ms. Background work paid for it: p95 E2E about 12.8 s → 26.3 s.
External admission (artifacts/p4/comparison-2026-08-31T21-15-28Z/result.json)
Native priority mixed burst p95 TTFT 297 ms. ServeScope 103 ms. Runtime waiting 83 → 0. All 240 background jobs finished. Background p95 E2E 19.1 s → 26.1 s. Output goodput 1869 → 1510 tok/s.
The recorded admission run never halved the concurrency limit (decrease_count = 0) because vLLM waiting stayed at zero. The improvement came from bounded admission itself.
An earlier interactive-only sweep did not find a clean saturation cliff.
Limits
- Local lab on one GPU.
- Live browser comparison is presentation evidence. Committed artifacts are the measured result.
- Does not implement a vLLM scheduler or CUDA kernels.